When agents write the code, who verifies the outcome?
SIMPLEX INSIGHTS · AGENTIC ENGINEERING, KNOWLEDGE & CONTROL
Imagine an agentic development pod completing a feature overnight. The user interface looks convincing. The build is green. Tests have passed. In the morning, the product owner has a tidy summary and a pull request ready to review.
But has anyone checked that the feature respects the organisation’s data-handling rules? Does it enforce the right customer permissions? Are the tests proving the business requirement—or merely confirming that the code behaves as its generating agent expected?
This is a hypothetical scenario, but it captures the next challenge in AI-assisted software delivery. The real question is no longer only how quickly agents can produce code. It is how reliably an organisation can prove that the resulting software works, is permitted and can be operated safely.
The software factory changes roles before it removes them
In its May 2026 article, McKinsey describes an agentic delivery model in which agents can progress structured requirements, designs, code and tests while people review outputs, resolve ambiguity and improve the operating system around them. Its account of smaller, highly skilled delivery pods is a picture of early practice—not a guaranteed team-size reduction for every organisation.
Google’s 2025 DORA research adds a useful qualification: AI amplifies the strengths and weaknesses of the surrounding organisation. Faster generation creates value only when architecture, teamwork, testing and delivery controls keep up.
In that environment, familiar roles do not necessarily disappear. Their emphasis changes:
- Product and domain owners become more precise about desired outcomes, acceptance criteria, priorities and decisions that agents must not make.
- Architects and technical leads define the boundaries: modular design, integration contracts, approved patterns, non-functional requirements and where exceptions require review.
- Software engineers move further towards shaping tasks, orchestrating agents, reviewing difficult logic, managing dependencies and improving the automated delivery system itself.
- Quality engineers design independent verification, explore failure scenarios and challenge assumptions the generating agent may have carried into its own tests.
- Security, risk and compliance specialists translate obligations into testable controls where possible, manage exceptions and retain authority over interpretations and risk acceptance.
This is not an argument that every person becomes an “AI supervisor”. Domain expertise, sound engineering and critical thinking matter more, not less. A factory that produces changes continuously also needs a clear human answer to a simple question: who owns the outcome?
Knowledge is production infrastructure, not a pile of documents
An agent can produce code quickly while being wrong about why the system exists, which integration is authoritative, or which restrictions apply. The problem is often not a lack of model capability. It is missing or contradictory organisational context.
McKinsey argues for treating a connected knowledge infrastructure as a foundation for agent autonomy. Its examples connect requirements, architectural decisions, repositories, incidents and compliance rules, rather than asking humans to reconstruct the story at every handoff. That is a useful direction, but it does not require an organisation to build an elaborate knowledge graph on day one.
A credible starting point is a curated, version-controlled knowledge base that agents can access within their permissions. It should include:
- Business intent: product goals, accepted requirements, user journeys, definitions and decision owners.
- Engineering truth: architecture decision records, API contracts, approved libraries, coding standards and reusable components.
- Control requirements: data classification, security baselines, privacy constraints, approval thresholds and mapped policy owners.
- Operational learning: incidents, failed tests, known limitations and the reasons earlier designs were accepted or rejected.
For each important item, know its owner, version, last review date and authoritative source. Retire conflicting material. Make sensitive information available only on a need-to-know basis. Retrieved knowledge should inform an agent; it should not silently become permission to take actions.
Verification gate one: does the software actually work?
An AI agent can generate a feature and generate tests that agree with that feature. Green test results are useful evidence, but they are not independent proof that the business problem was understood correctly. If the original requirement was ambiguous, code and tests can share the same mistake.
Functional verification therefore starts outside the generating agent’s assumptions. Business owners and quality engineers define observable acceptance criteria, including negative cases and the behaviour that must not occur. The delivery pipeline then checks the result at several levels:
- Unit and contract tests check the logic and interfaces that other components depend upon.
- Integration and end-to-end tests confirm that real workflows operate across the relevant services and data boundaries.
- Regression, accessibility, performance and resilience tests check qualities that a functional happy-path demonstration can miss.
- Independent review and controlled user acceptance examine whether the feature solves the intended problem, especially for consequential changes.
The NIST Secure Software Development Framework sets out high-level practices for building security into software development rather than adding it after coding is complete. The exact checks should be proportionate to the system’s criticality; the key is that acceptance is based on evidence, not on the generating agent’s assurance.
Verification gate two: is it allowed?
Now consider a feature that works perfectly but calls an unapproved external service, gives an agent excessive permissions, introduces a prohibited dependency, or exports data outside an agreed boundary. Functional correctness alone is not enough.
Policy as code turns selected organisational requirements into versioned, executable rules. For example, a delivery pipeline could automatically reject a change if a service requests unrestricted production credentials, an infrastructure definition exposes private data, a dependency fails an approved-source rule, or a high-risk deployment lacks a named approval.
Projects such as Open Policy Agent show how policy decisions can become part of CI/CD, infrastructure configuration and runtime enforcement. Rules can be tested like software, linked to their owners and changed through review.
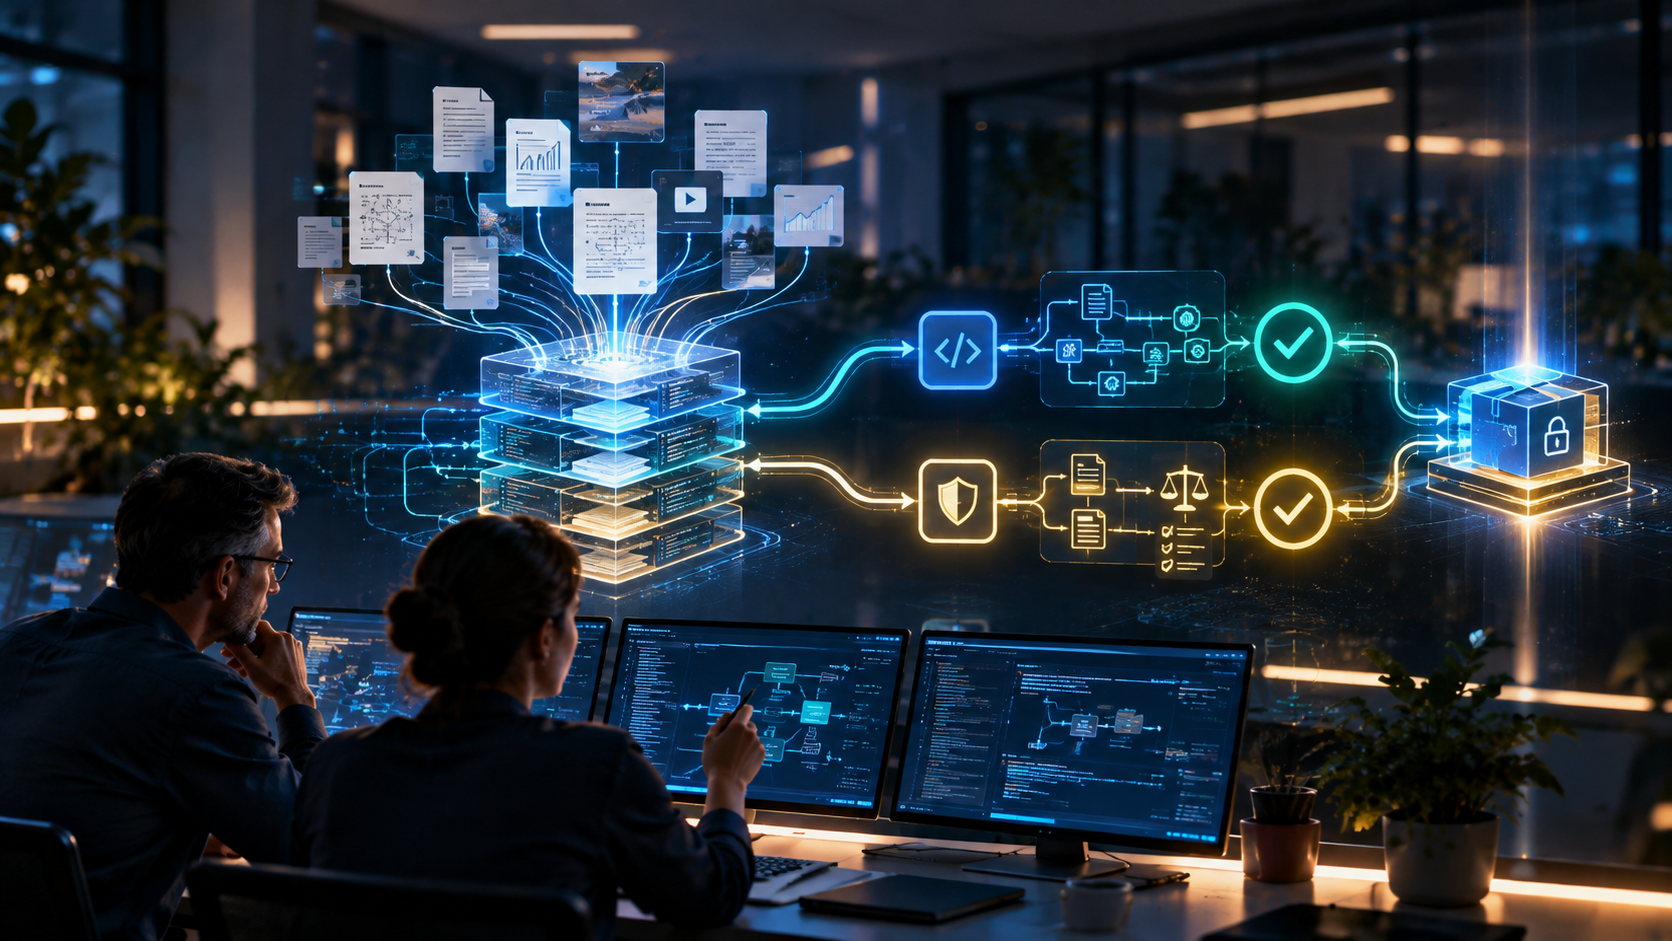
A practical factory should run functional checks and policy checks as separate, complementary gates. For each release, preserve evidence of the requirements and tests used, the policy versions applied, any exceptions, the reviewer and the artefact approved for deployment. SLSA’s software-provenance guidance provides a useful model for tracing how a software artefact was produced.
This becomes especially important as agents gain tool access. The OWASP Top 10 for Agentic Applications describes risks such as goal hijacking, tool misuse and identity or privilege abuse. Least-privilege execution environments and human approval for high-impact actions belong in the factory design, not just in the agent prompt.
There is an important limit: passing automated policy checks does not certify GDPR, EU AI Act or contractual compliance. A policy can only enforce what has been translated accurately into a rule and what the available evidence can measure. Legal interpretation, judgement, exceptions and accountability remain human responsibilities.
A factory should produce a verifiable change package
Rather than asking an agent to “build and deploy”, give an agentic pod a more disciplined assignment: understand the scoped request, use approved context, propose a plan, implement in an isolated workspace, and return a reviewable change package.
That package should contain the proposed code, the requirement and architecture references, tests and results, security and policy findings, known limitations, and an explanation of what needs human approval. The system—not the agent’s confidence—should decide which mandatory gates have passed.
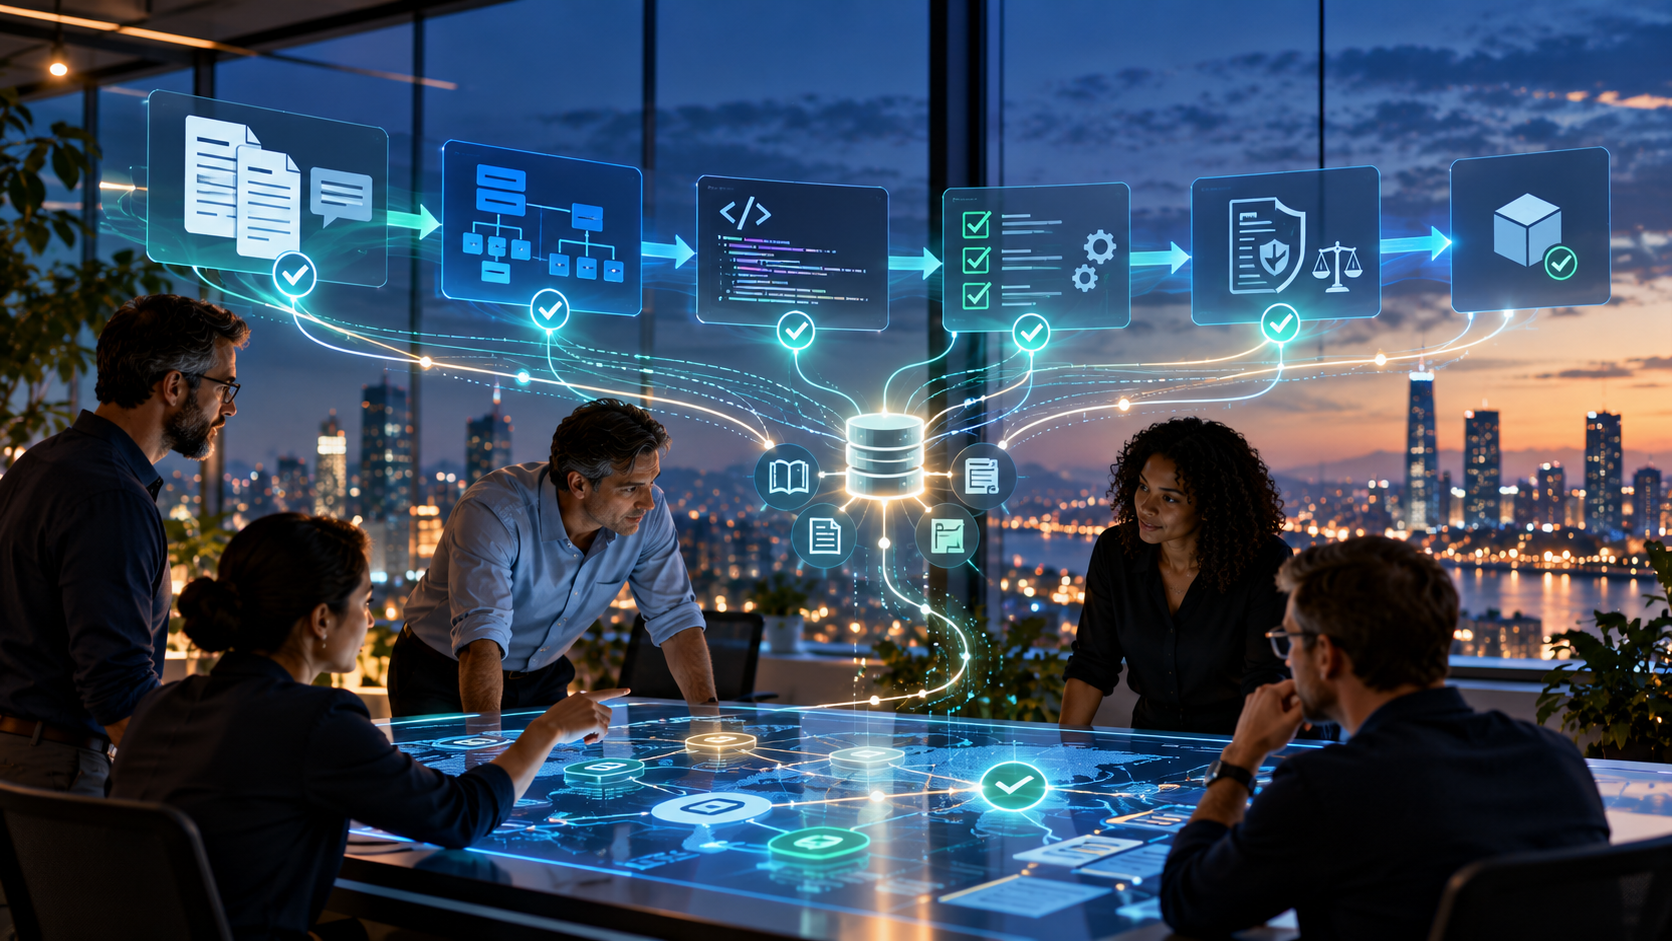
A responsible release process can then follow a simple sequence: define → contextualise → build → verify functionality → verify controls → approve → deploy and monitor. Failed checks return work for correction. Accepted exceptions are explicitly recorded. Monitoring feeds lessons back into the knowledge base so the next cycle starts better informed. That evidence matters for continuity too: when a provider or tool becomes unavailable mid-task, people need a reliable record of what happened and how to resume safely. We examined that question in an earlier Simplex Insight, If your AI stopped tomorrow, could your business still operate?
Start with one pod, not an entire software factory
An organisation does not need to automate its whole software delivery life cycle to learn. Choose one bounded application change, one small agentic pod, a clearly owned specification and a secure test environment.
Give the pod a short, curated knowledge set and a handful of meaningful policy rules. Run the two verification gates. Compare results against a conventional delivery baseline. Measure outcomes such as lead time to an accepted change, escaped defects, review effort, policy exceptions, rework and cost—not simply lines of generated code or the number of agents running overnight.
In an agentic software factory, speed is an advantage. Trustworthy knowledge, independent verification and clear accountability determine whether that speed becomes sustainable value.
Where Meridian fits
At Simplex, we are exploring the Meridian Software Factory as an early-stage extension of a wider approach to AI readiness, governed operation and continuous improvement. We are not presenting it as a finished factory product.
Our existing Meridian Readiness Assessments already offer a practical entry point: from strategic alignment and governance through engineering organisation, AI and agentic readiness, codebase design, and platform infrastructure. Before increasing autonomy, it is worth understanding whether those foundations are in place.
Is your engineering organisation ready for agentic delivery?
A Meridian Readiness Assessment can help identify architecture, knowledge, engineering and governance gaps before investing in a larger agentic software factory.
Further reading and sources
- McKinsey & Company — Rewiring software delivery for the agentic era (28 May 2026). Evolving delivery roles, connected knowledge and policy-as-code controls.
- Google DORA — 2025 State of AI-assisted Software Development (2025). AI as an amplifier of organisational capabilities and weaknesses.
- NIST SP 800-218 — Secure Software Development Framework (2022). Secure development practices across the software lifecycle.
- Open Policy Agent — Using OPA in CI/CD Pipelines. Executable policy enforcement and testing.
- OWASP — Top 10 for Agentic Applications (2026). Agent autonomy, tool misuse, trust boundaries and security risks.
- SLSA — Provenance specification. Verifiable build and source provenance for software artefacts.
Simplex Insight · Published 28 October 2026. The examples in this article are illustrative. This is general engineering and governance guidance, not legal advice or a certification of compliance.